


[Aug-2026] AI-300 Dumps are Available for Instant Access using Prep4sureGuide
AI-300 Dumps 2026 - New Microsoft AI-300 Exam Questions
NEW QUESTION # 36
Hotspot Question
You review the following Azure CLI command and the relevant Bicep excerpt.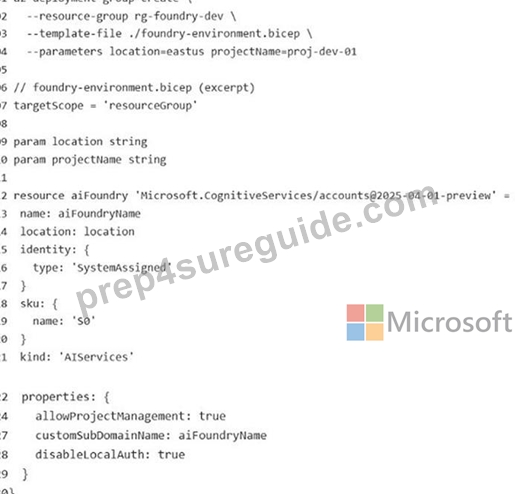
(Non-relevant sections are omitted.)
You need to validate what the snippet will do before it is merged. For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
NEW QUESTION # 37
You plan to filter your traces to identify issues while observing how the application is responding. The solution must not use an external knowledge base.
You need to select an evaluation metric.
Which built-in evaluator should you use?
- A. RelevanceEvaluator
- B. SimilarityEvaluator
- C. CoherenceEvaluator
- D. QAEvaluator
Answer: C
Explanation:
A multi-turn chatbot application intermittently produces responses that are grammatically correct and on-topic but contradict earlier turns in the conversation, creating a confusing user experience. CoherenceEvaluator measures exactly this: whether the flow of ideas across a multi-turn conversation is logically consistent and non-contradictory without requiring an external knowledge base. RelevanceEvaluator (option A) measures whether responses are topically on-point but often requires a reference context or knowledge base.
SimilarityEvaluator (option B) requires a reference answer for comparison. QAEvaluator (option C) is a composite evaluator for question-answering tasks that requires a ground-truth context document.
CoherenceEvaluator is the only option that works purely from the conversation history itself with no external knowledge base, perfectly matching the stated constraint and the multi-turn chatbot use case.
Microsoft Learn Reference Topic: Evaluate conversational AI applications in Microsoft Foundry - CoherenceEvaluator for multi-turn chatbots
NEW QUESTION # 38
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a mid-sized healthcare analytics company that provides population health dashboards and predictive insights to regional hospital systems across the United States.
Fabrikam Inc. customers rely on near real time analytics to monitor patient flow, staffing needs, and readmission risks. They use multiple traditional forecasting machine learning models for predictions.
Fabrikam Inc. has an established Microsoft Azure footprint. The company uses Jupyter Notebooks that run on a local server as the primary development environment. The data science team is experiencing scalability, asset management and code management issues with the current development platform. Fabrikam Inc. plans to migrate to a cloud-based development environment to mitigate the issues.
Additionally, the company plans to implement a Retrieval-Augmented Generation (RAG)-based chat application for client support. Leadership requires the application to be developed and deployed with a low operational risk.
Current Environment
Fabrikam Inc. operates a single Azure subscription that has the following components:
* Azure Data Lake Storage Gen2 that contains de-identified clinical and operational datasets
* Azure AI Search indexing curated analytical documents and reference materials
* A small set of Python-based training scripts maintained by data scientists
* Azure OpenAI Service with deployed foundational models
* A Microsoft Foundry resource for building a RAG-based solution
Evaluation data has manually defined expected responses.
The current challenges faced by the data science team include the following:
* Model training jobs are run manually from notebooks.
* Experiment tracking is inconsistent
* Model versions are registered without standardized metadata.
* Deployment is performed manually by data scientists, with limited rollback capability.
* The team has no standardized evaluation process for generative AI outputs.
The environment currently allows public network access. Authentication relies on user accounts rather than managed identities. Compute targets are manually created and shared across experiments. This has led to resource contention during peak usage.
Business Requirements
Fabrikam Inc. has the following business requirements for the modernization initiative:
* Provide a conversational interface that answers analytics questions by using internal documents and datasets.
* Ensure that sensitive healthcare-related data is not exposed outside the Fabrikam Inc. Azure tenant.
* Enable repeatable and auditable model training and deployment processes.
* Support experimentation to compare prompt strategies and fine-tuned models.
* Align the model with the ranked preferences and optimize behavior for the long term.
* Minimize disruption to existing analytics workloads during rollout.
Technical Requirements
To support the business goals, Fabrikam Inc. identifies these technical requirements:
* Use Azure Machine Learning workspaces to centrally manage data assets, models, and environments.
* Implement experiment tracking and model versioning for all training jobs.
* Orchestrate training and evaluation by using pipelines rather than manually running notebooks.
* Deploy traditional machine learning models with support for staged rollout and rollback.
* Improve RAG-based solution output quality.
* Use the existing evaluation datasets that are based on real data with input-output pairs.
* Apply advanced fine-tuning techniques only when prompt engineering is insufficient Issues and Constraints Fabrikam Inc. must comply with internal security policies that require the company to restrict network access and avoid long-lived secrets. The data science team has limited Azure DevOps experience, so solutions must favor managed services and automation over custom infrastructure.
Cost predictability is important. Leadership prefers serverless or managed compute options where possible but is willing to approve dedicated compute for stable production workloads.
Problem Statement
Fabrikam Inc. must design and implement an Azure-based AI operations solution that enables reliable training, evaluation, deployment, and iteration of generative AI models. The solution must support experimentation and gradual rollout while ensuring governance, security, and operational stability. The data science and platform teams must collaborate to deliver this solution by using Azure Machine Learning and Microsoft Foundry capabilities.
You need to make model training repeatable and auditable to address Fabrikam Inc.'s current environment challenges and technical requirements. What should you use?
- A. Serverless execution by using Azure Functions
- B. Workflow automation by using Azure Logic Apps
- C. Training pipelines in Azure Machine Learning
- D. Scheduled notebook runs by using Azure Machine Learning jobs
Answer: C
Explanation:
Azure Machine Learning (AML) training would be best. While the other options can execute code, they lack the native machine learning operations (MLOps) capabilities required for enterprise auditing and repeatability.
Azure ML pipelines are purpose-built for machine learning workflows. They natively solve your tracking and auditing requirements.
Built-in Lineage: Automatically tracks data inputs, code versions, environments, and output models.
Native Component Reuse: Steps are modular, containerized, and easily shared across teams.
Data Caching: Skips completed steps if inputs have not changed, saving time and compute costs.
Scenario, Technical Requirements:
Implement experiment tracking and model versioning for all training jobs.
Orchestrate training and evaluation by using pipelines rather than manually running notebooks.
Problem Statement
Fabrikam Inc. must design and implement an Azure-based AI operations solution that enables reliable training, evaluation, deployment, and iteration of generative AI models.
Reference:
https://medium.com/data-for-ai/mlops-with-a-feature-store-8dabc845584a
NEW QUESTION # 39
An Azure Machine Learning workspace processes sensitive training data.
The workspace must NOT be accessible from the public internet.
You need to restrict network access.
Which configuration should you implement?
- A. Private endpoints
- B. Network security groups
- C. Azure Firewall rules
- D. Service endpoints
Answer: A
Explanation:
To ensure an Azure Machine Learning (AML) workspace handling sensitive data is not accessible from the public internet, you must disable the Public Network Access flag and implement Private Endpoints. This configuration creates a private link between your Azure Virtual Network (VNet) and the workspace, ensuring traffic never traverses the public internet.
Reference:
https://www.azadvertizer.net/azpolicyadvertizer/438c38d2-3772-465a-a9cc-7a6666a275ce.html
NEW QUESTION # 40
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You manage an Azure Machine Learning workspace. The Python script named script.py reads an argument named training_data. The training_data argument specifies the path to the training data in a file named dataset1.csv.
You plan to run the script.py Python script as a command job that trains a machine learning model.
You need to provide the command to pass the path for the dataset as a parameter value when you submit the script as a training job.
Solution: python script.py dataset1.csv
Does the solution meet the goal?
- A. Yes
- B. No
Answer: B
Explanation:
Correct:
* python script.py --training_data ${{inputs.training_data}}
The scipt is named script.py.
For the parameter use ${{inputs.training_data}}
Incorrect:
* python script.py --training_data dataset1.csv
* python script.py dataset1.csv
* python train.py --training_data training_data
Note: Read a TabularDataset, Example
In the Input object, specify the type as AssetTypes.MLTABLE, and mode as InputOutputModes.DIRECT:
* Details omitted*
job = command(
code="./src", # Local path where the code is stored
*-> command="python train.py --inputs ${{inputs.input_data}}",
inputs=my_job_inputs,
environment="<environment_name>:<version>",
compute="cpu-cluster",
)
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-read-write-data-v2
NEW QUESTION # 41
A data science team completes multiple training runs within an experiment by using MLflow.
The team wants to store a selected model in Azure Machine Learning so that it can be versioned and deployed later.
The model must be versioned centrally for reuse across environments.
You need to version the trained model.
Which two actions should you perform? Each correct answer presents part of the solution. NOTE: Each correct selection is worth one point. Choose two .
- A. Locate and capture the model artifacts from the outputs of the training run.
- B. Tag the training experiment with a name.
- C. Register the model in the Azure Machine Learning workspace.
- D. Export the model files to local storage.
Answer: A,C
Explanation:
MLflow training runs produce model artifacts - the serialized model files, conda environment, and MLmodel specification - stored in the run ' s outputs folder. These artifacts are transient run outputs but are not yet a versioned, named model that can be deployed. To make the model a first-class, versioned, deployable artifact, you must explicitly register it. Locating artifacts from the run (action A) is necessary because you need the run ' s artifact URI, typically in the form runs:/run_id/model, to register from.
Registering in the AML workspace (action B) creates an entry in the model registry with a name and auto- incremented version, making the model discoverable, governable, and deployable across environments.
Tagging the experiment (option C) does not version the model. Exporting to local storage (option D) removes the model from Azure ML ' s managed infrastructure, losing lineage and governance.
Microsoft Learn Reference Topic: Register MLflow models in the Azure Machine Learning model registry
NEW QUESTION # 42
You manage an Azure Machine Learning workspace. You build a model for which you must configure a Responsible Al dashboard.
Based on what you learn from the dashboard, you must perform the following activities:
- Determine what must be done to get a desirable outcome from the
model.
- Identify the features that have the most direct effect on your
outcome of interest.
You need to select the components to use for the Responsible Al dashboard configuration.
Which two components should you add? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
- A. explanation
- B. error analysis
- C. causal
- D. counterfactuals
Answer: C,D
Explanation:
To meet your requirements, you should configure the Responsible AI (RAI) dashboard with the Counterfactuals (What-If) and Causal Analysis components.
1. Counterfactuals (What-If)
Purpose: This component helps you figure out how to change the model's output to a target result for specific instances.
Mechanism: It generates counterfactual examples (the closest possible data points) that yield a different, desirable outcome. For example, it can answer: "What is the minimum amount this user's income needs to increase for their loan application to be approved?"
2. Causal Analysis
Purpose: This component estimates the direct causal effect of specific "treatment" features on your ultimate outcome of interest.
Mechanism: Unlike standard feature importance (which only shows correlation), causal inference answers deep prescription questions. It separates pure correlation from true causation to tell you exactly how changing a real-world policy or feature directly moves your target metric.
Reference:
https://docs.azure.cn/en-us/machine-learning/concept-responsible-ai-dashboard?view=azureml-api-2
NEW QUESTION # 43
Hotspot Question
A team trains an MLflow model that scores customer churn risk. The model will be consumed by different downstream systems.
One system requests predictions synchronously during customer interactions.
Another system submits files containing millions of records for scheduled scoring.
You need to deploy the model by using managed inference options that match each usage pattern.
Which option should you use for each usage pattern? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
NEW QUESTION # 44
Hotspot Question
You are reviewing a dataset that will be used for an advanced fine-tuning job in Microsoft Foundry.
The fine-tuning job uses preference comparison data.
You review the following dataset excerpt.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
NEW QUESTION # 45
Hotspot Question
You use Azure Machine Learning to implement hyperparameter tuning for an Azure ML Python SDK v2-based model training.
Training runs must terminate when the primary metric is lowered by 25 percent or more compared to the best performing run.
You need to configure an early termination policy to terminate training jobs.
Which values should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
NEW QUESTION # 46
Drag and Drop Question
You have an existing GitHub repository containing Azure Machine Learning project files.
You need to clone the repository to your Azure Machine Learning shared workspace file system.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
NOTE: More than one order of answer choices is correct. You will receive credit for any of the correct orders you select.
Answer:
Explanation:
NEW QUESTION # 47
A team develops multiple AI applications in Microsoft Foundry that rely on shared prompt templates.
The team requires a centralized way to track, version, and reuse prompt content across projects.
You need to recommend a solution to track and reuse prompt content.
Which approach should you recommend?
- A. Embed prompts directly in application configuration files.
- B. Store prompts as versioned files in a Git repository.
- C. Register prompts as datasets in the Azure Machine Learning workspace.
- D. Persist prompts in Azure Blob Storage with folder-level organization.
Answer: B
Explanation:
In Microsoft Foundry, centralizing prompt templates in a Git repository (such as GitHub) is a recommended GenAIOps practice to ensure consistency, versioning, and reuse across multiple AI applications.
Storing prompts as versioned files in a Git repository is an excellent approach for Microsoft Foundry applications. It treats prompts like code (PromptOps), enabling clear audit trails, peer reviews via Pull Requests, and easy rollbacks.
To make this centralized system effective, you should consider these three components:
Centralized Repository: Use a single "Prompt Bank" repo where templates are stored in a structured format like JSON or YAML. Include metadata like model version, temperature, and input variables.
Prompt Registry / SDK: Develop a small internal utility (or use a tool like Azure AI Studio's Prompt Flow) that allows applications to fetch the "latest" or a "tagged" version of a prompt via API or as a Git submodule.
CI/CD Integration: Automate testing so that when a prompt file is updated, it triggers a "prompt evaluation" pipeline to ensure the change doesn't degrade AI performance across the dependent projects.
Reference:
https://www.getmaxim.ai/articles/best-practices-for-prompt-management-in-ai-applications
NEW QUESTION # 48
A team is working in Microsoft Foundry to test and compare large language model (LLM) prompt variants in a development environment.
The team requires consistent inputs to evaluate prompt variants without relying on live user traffic.
You need to create a controlled evaluation of input data.
Which action should you perform first?
- A. Apply a blocklist.
- B. Configure content filters.
- C. Enable observability metrics.
- D. Generate synthetic interaction data.
Answer: D
Explanation:
The team cannot rely on live user traffic for evaluation because it would make results non-reproducible and could expose users to untested prompts. Synthetic data generation within Microsoft Foundry allows the team to produce diverse, representative input examples that simulate real user queries without any live traffic risk, giving a stable, consistent test set evaluated under identical conditions. Option B (content filters) and Option C (blocklists) are safety controls applied at inference time, not evaluation inputs. Option D (observability metrics) is a monitoring capability for production systems. With synthetic data, the team can construct edge cases, varied phrasings, and domain-specific scenarios that would take months to accumulate organically from real users, directly enabling the controlled evaluation the question requires without any dependency on live traffic.
Microsoft Learn Reference Topic: Evaluate generative AI apps with synthetic data - Microsoft Foundry prompt evaluation
NEW QUESTION # 49
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You manage an Azure Machine Learning workspace. The Python script named script.py reads an argument named training_data.
The training_data argument specifies the path to the training data in a file named dataset 1. csv.
You plan to run the script.py Python script as a command job that trains a machine learning model.
You need to provide the command to pass the path for the dataset as a parameter value when you submit the script as a training job.
Solution: python train.py --training_data training_data
Does the solution meet the goal?
- A. Yes
- B. No
Answer: B
Explanation:
This solution fails for two reasons. First, the script filename is wrong: the scenario specifies script.py, but the proposed solution calls train.py. This alone disqualifies the solution. Second, the input reference syntax is incorrect. In Azure ML SDK v2 command jobs, input values are injected into the command string using a placeholder syntax with double curly braces around inputs.name. The value training_data without the placeholder is just a string literal and is not resolved to the actual file path of the input data asset. The correct command syntax uses the proper placeholder so Azure ML can resolve the registered data asset and provide its local path to the script at runtime. Both errors - wrong script name and missing placeholder syntax - make this solution non-functional.
Microsoft Learn Reference Topic: Submit training jobs as command jobs in Azure Machine Learning Python SDK v2
NEW QUESTION # 50
A team plans to deploy a large foundation model in Microsoft Foundry as part of a new enterprise AI capability.
Different business units across the team's organization will access the model from various internal applications.
You need to deploy a foundation model by minimizing latency.
Which deployment type should you use?
- A. Data Zone Batch
- B. Developer
- C. Global Batch
- D. Data Zone Standard
Answer: D
Explanation:
In this scenario, Data Zone Standard is the most appropriate deployment type for minimizing latency.
While other options cater to high-volume or testing needs, Data Zone Standard is specifically designed for real-time application traffic with a balance of performance and regional availability.
Why Data Zone Standard is the Correct Choice
Real-Time Processing: Unlike the "Batch" options, Data Zone Standard is built for synchronous, real-time requests from internal applications, ensuring the low latency required for interactive user experiences.
Dynamic Routing: It dynamically routes traffic to the most available data centers within a specific Microsoft-defined data zone (e.g., US or EU), which helps maintain responsiveness even if one region experiences high load.
Higher Quotas: It offers higher default throughput (TPM/RPM) than standard regional deployments, allowing multiple business units to access the model simultaneously without hitting restrictive limits that could cause queuing and latency spikes.
Incorrect:
[Not A]
Developer: This deployment type is typically used for initial testing, prototyping, and experimentation rather than high-performance production workloads accessed by many different business units.
[Not B, not D]
Global Batch & Data Zone Batch: These are asynchronous deployment types. They are designed for processing large datasets (like document summaries or mass sentiment analysis) with a 24- hour turnaround time. While they are 50% cheaper, they are not suitable for real-time applications where immediate response is needed.
Reference:
https://learn.microsoft.com/en-us/azure/foundry/foundry-models/concepts/deployment-types
NEW QUESTION # 51
Drag and Drop Question
A team manages prompts that are used by a generative AI application built on Microsoft Foundry.
Multiple developers contribute prompt updates, and changes must be reviewed and tracked over time.
The team requires that:
- Prompt changes are reviewed before being applied to the version in
production.
- Previous prompt versions can be restored if issues occur.
- Prompt updates follow the same governance practices as the
application code.
You need to implement a controlled process for managing and updating prompts in production.
How should you manage prompt updates to meet the requirements? To answer, move the appropriate actions to the correct requirements. You may use each action once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
NEW QUESTION # 52
Hotspot Question
You have an Azure Machine Learning workspace named Workspace1.
You plan to train an image classification model by using Automated ML in Workspace1.
You need to complete the provided Azure Machine Learning Python SDK v2 code to bring labeled image data as input for model training.
How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Box 1: azure.ai.ml.constants
azure.ai.ml.constants is the official SDK v2 submodule where the AssetType enum resides.
Box 2: MLTABLE
AssetType.MLTABLE: Automated ML for Computer Vision tasks (such as image classification and object detection) specifically requires your input data and corresponding label annotations to be provided via an MLTable asset type. This structure points to a folder containing your dataset configurations and your .jsonl bounding box or classification files.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-auto-train-image-models
NEW QUESTION # 53
A team runs training jobs by using multiple Azure Machine Learning pipelines.
The team must ensure that all runs use the same Python packages and system libraries. The solution must allow dependency updates to be versioned without modifying training code.
You need to configure the workspace so that runtime dependencies are consistent and reusable.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
Answer:
Explanation:
Explanation:
To ensure runtime dependencies are consistent and reusable, first create a conda.yaml or requirements.txt file that lists all Python packages and system libraries required by your training code - this file is the single source of truth for your runtime. Next, create an Environment object using the Azure ML Python SDK v2 with a name and reference to the conda.yaml file, specifying the base Docker image. Then register the Environment by calling ml_client.environments.create_or_update, which publishes it to the workspace registry with an auto-incremented version. Finally, reference the registered environment by name and version in all pipeline job steps. Azure ML will build or retrieve the cached Docker image and use it as the execution container. This approach means updating dependencies only requires modifying the conda.yaml and registering a new version - training code remains unchanged.
Microsoft Learn Reference Topic: Create and manage Azure Machine Learning environments - Reusable curated environments
NEW QUESTION # 54
You deploy a model to production but do not have labeled data available for evaluating prediction accuracy. However, you must monitor model health continuously. What is the BEST strategy?
- A. Use data drift detection
- B. Monitor accuracy metrics
- C. Perform manual evaluation only
- D. Disable monitoring
Answer: A
Explanation:
When labeled data is unavailable, traditional accuracy metrics cannot be computed. Data drift detection monitors changes in input data distribution, serving as a proxy for potential performance degradation. This allows early detection of issues before labeled data becomes available.
NEW QUESTION # 55
Hotspot Question
You manage a Retrieval-Augmented Generation (RAG) system that uses Azure AI Search to retrieve documents from an indexed knowledge base.
The system must support the following retrieval requirements:
- Queries that include exact policy identifiers must return matching
documents even when semantic similarity is low.
- Natural-language questions must prioritize semantically relevant
documents even when keywords are not an exact match.
You need to configure the retrieval approach to meet the requirements.
How should you configure the retrieval behavior for each requirement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
NEW QUESTION # 56
Hotspot Question
You have an Azure Machine Learning workspace.
You plan to set up logging and tracking experiments by using MLflow Tracking.
You need to log the accuracy as a numerical value and the training loss as a plot.
How should you complete the commands? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: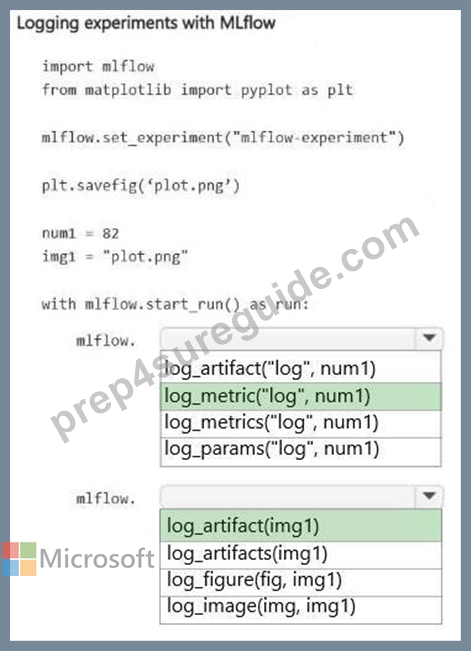
Explanation:
Box 1: log_metric("log", num1)
Log Numerical Metrics
To track a single numerical value that changes over time (like accuracy or evaluation scores), you use the mlflow.log_metric() function. This enables Azure Machine Learning to plot the value on a performance graph automatically.
Box 2: log_artifact(img1)
Log Plots and FilesTo save external files, images, or plots generated during training, you use the mlflow.log_artifact() function. This uploads the specified file (in this case, your saved Matplotlib image) to the run's artifact storage.
Reference:
https://levelup.gitconnected.com/mlflow-made-easy-your-beginners-guide-bf63f8fed915
NEW QUESTION # 57
A data science team plans to evaluate multiple hyperparameter values automatically while training a model in Azure Machine Learning.
The tuning process must run multiple training trials without manually modifying the training script for each run.
You need to automate hyperparameter tuning for the training job.
What should you do?
- A. Create a tuning job that runs multiple trials with different parameter values.
- B. Adjust hyperparameters after model deployment.
- C. Duplicate the training script for each parameter combination.
- D. Manually change hyperparameter values between training runs.
Answer: A
NEW QUESTION # 58
Drag and Drop Question
You use Azure Machine Learning to deploy a model as a real-time web service.
You need to create an entry script for the service that ensures that the model is loaded when the service starts and is used to score new data as it is received.
Which functions should you include in the script? To answer, drag the appropriate functions to the correct actions. Each function may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
NEW QUESTION # 59
......
Microsoft AI-300 Exam Practice Test Questions: https://www.prep4sureguide.com/AI-300-prep4sure-exam-guide.html
Free AI-300 Braindumps Download Updated: https://drive.google.com/open?id=1uzyPmT8DajqT95pP8B10Nkb4hexSnCz2