


[2026] New DP-600 exam dumps Use Updated Microsoft Exam
Verified DP-600 Dumps Q&As - DP-600 Test Engine with Correct Answers
Microsoft DP-600 Exam Syllabus Topics:
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 91
You have a Fabric workspace named Workspace 1 that contains a dataflow named Dataflow1. Dataflow! has a query that returns 2.000 rows. You view the query in Power Query as shown in the following exhibit.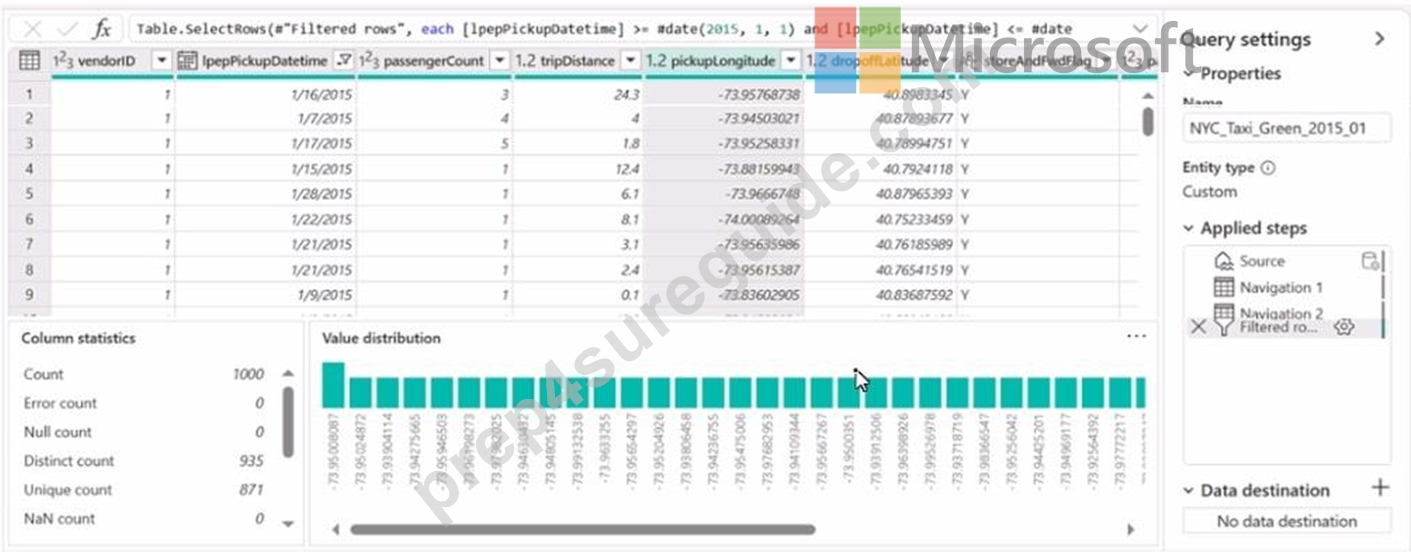
What can you identify about the pickupLongitude column?
- A. The column has missing values.
- B. All the table rows are profiled.
- C. There are 935 values that occur only once.
- D. The column has duplicate values.
Answer: D
Explanation:
The pickupLongitude column has duplicate values. This can be inferred because the 'Distinct count' is 935 while the 'Count' is 1000, indicating that there are repeated values within the column. Reference = Microsoft Power BI documentation on data profiling could provide further insights into understanding and interpreting column statistics like these.
NEW QUESTION # 92
Which workspace rote assignments should you recommend for ResearchReviewersGroupl and ResearchReviewersGroupZ? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.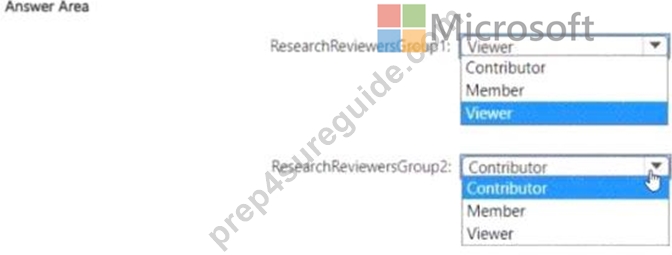
Answer:
Explanation: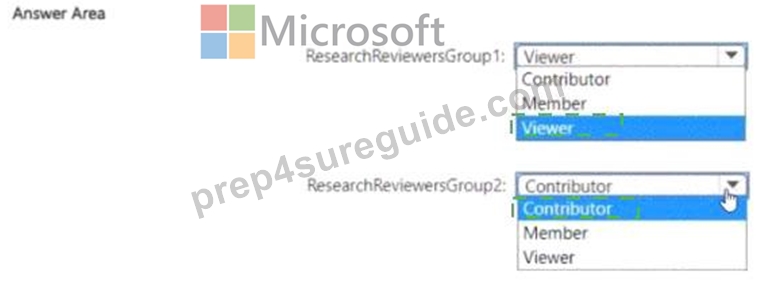
Explanation: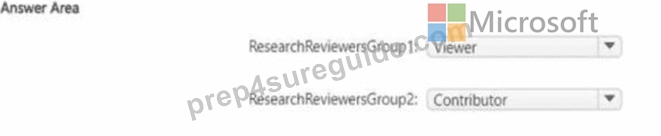
NEW QUESTION # 93
You have a Microsoft Power Bl project that contains a file named definition.pbir. definition.pbir contains the following JSON.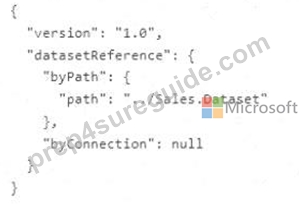
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.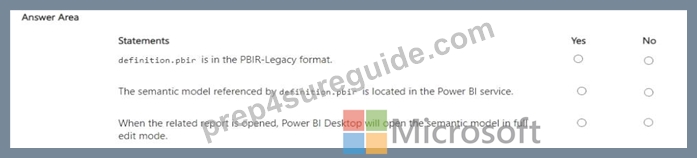
Answer:
Explanation: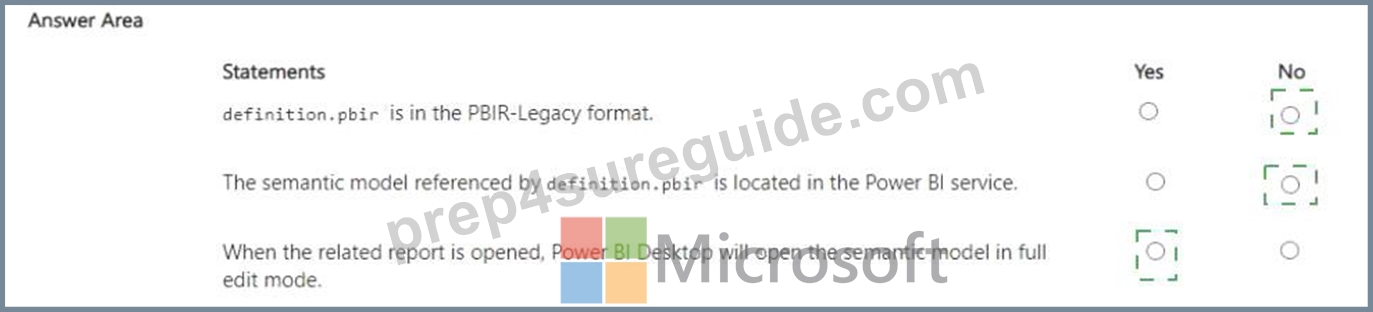
Explanation: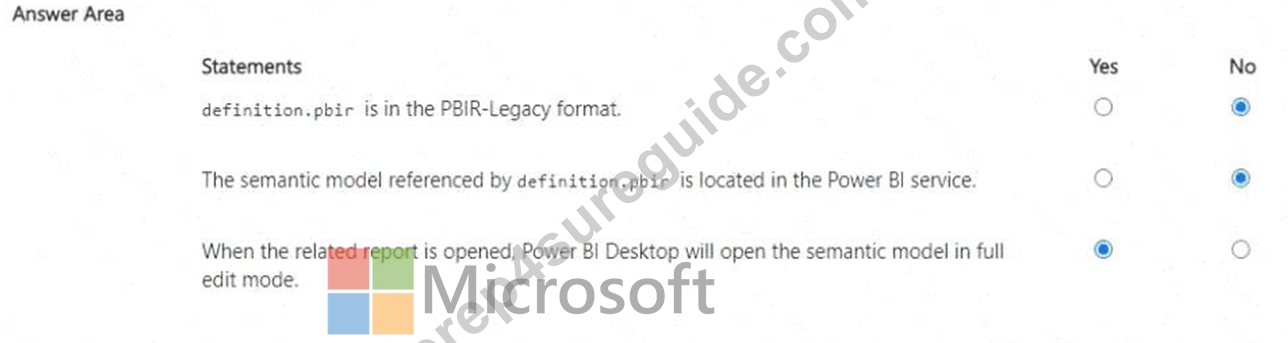
NEW QUESTION # 94
You have a Microsoft Power Bl semantic model that contains measures. The measures use multiple calculate functions and a filter function.
You are evaluating the performance of the measures.
In which use case will replacing the filter function with the keepfilters function reduce execution time?
- A. when the filter function references a measure
- B. when the filter function references columns from multiple tables
- C. when the filter function references a column from a single table that uses Import mode
- D. when the filter function uses a nested calculate function
Answer: C
Explanation:
The KEEPFILTERS function modifies the way filters are applied in calculations done through the CALCULATE function. It can be particularly beneficial to replace the FILTER function with KEEPFILTERS when the filter context is being overridden by nested CALCULATE functions, which may remove filters that are being applied on a column. This can potentially reduce execution time because KEEPFILTERS maintains the existing filter context and allows the nested CALCULATE functions to be evaluated more efficiently.
References: This information is based on the DAX reference and performance optimization guidelines in the Microsoft Power BI documentation.
NEW QUESTION # 95
Which syntax should you use in a notebook to access the Research division data for Productlinel?
- A.

- B.
- C.

- D.
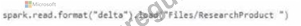
Answer: D
NEW QUESTION # 96
You have a Fabric tenant that contains a semantic model named Model1. Model1 uses Import mode. Model1 contains a table named Orders. Orders has 100 million rows and the following fields.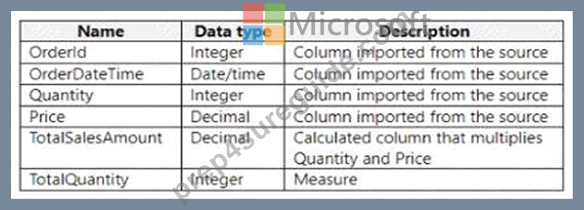
You need to reduce the memory used by Model! and the time it takes to refresh the model. Which two actions should you perform? Each correct answer presents part of the solution. NOTE: Each correct answer is worth one point.
- A. Convert Quantity into the Text data type.
- B. Split OrderDateTime into separate date and time columns.
- C. Replace TotalSalesAmount with a measure.
- D. Replace TotalQuantity with a calculated column.
Answer: B,C
Explanation:
To reduce memory usage and refresh time, splitting the OrderDateTime into separate date and time columns (A) can help optimize the model because date/time data types can be more memory-intensive than separate date and time columns. Moreover, replacing TotalSalesAmount with a measure (D) instead of a calculated column ensures that the calculation is performed at query time, which can reduce the size of the model as the value is not stored but calculated on the fly. References = The best practices for optimizing Power BI models are detailed in the Power BI documentation, which recommends using measures for calculations that don't need to be stored and adjusting data types to improve performance.
NEW QUESTION # 97
Hotspot Question
You have a Fabric tenant that contains the semantic model shown in the following exhibit.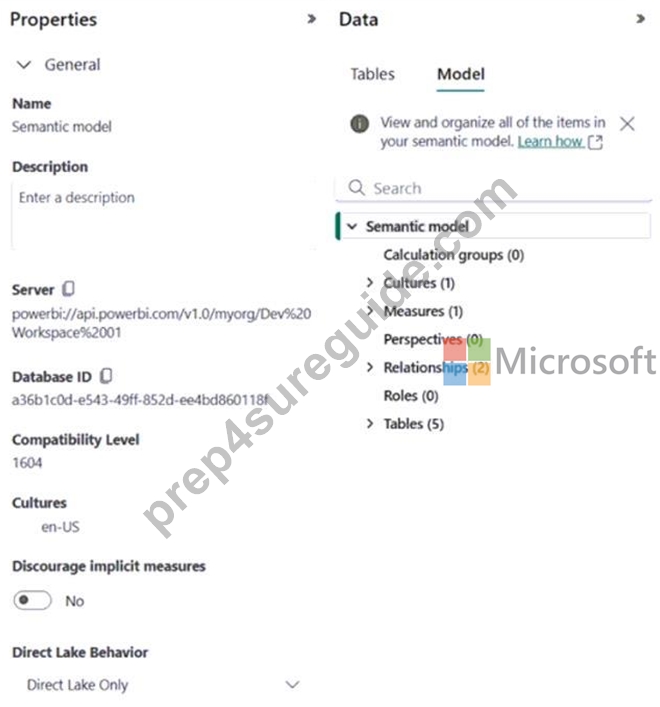
Use the drop-down menus to select the answer choice that completes each statement based on the information presented in the graphic.
NOTE: Each correct selection is worth one point.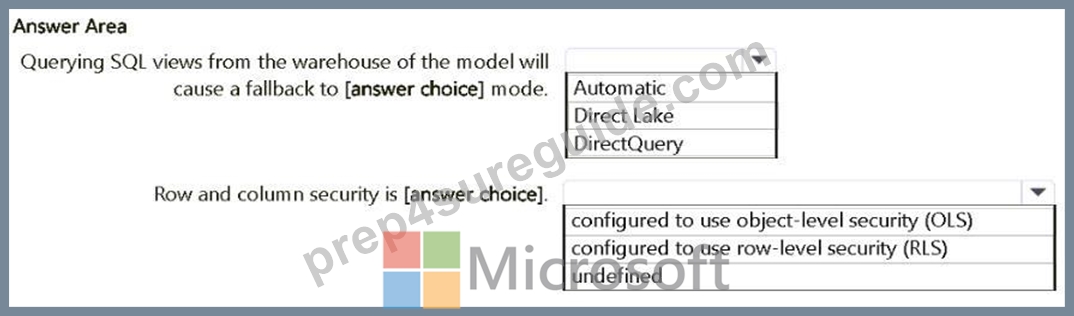
Answer:
Explanation: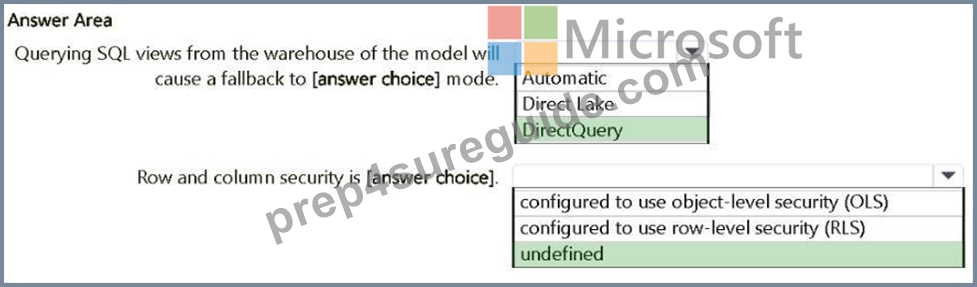
NEW QUESTION # 98
You have a Fabric tenant that uses a Microsoft tower Bl Premium capacity. You need to enable scale-out for a semantic model. What should you do first?
- A. At the semantic model level, set Large dataset storage format to On.
- B. At the tenant level, set Create and use Metrics to Enabled.
- C. At the semantic model level, set Large dataset storage format to Off.
- D. At the tenant level, set Data Activator to Enabled.
Answer: A
NEW QUESTION # 99
You have a Fabric tenant that contains a lakehouse named Lakehouse1. Lakehouse1 contains a table named Nyctaxi_raw. Nyctaxi_raw contains the following columns.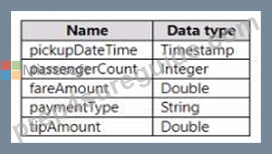
You create a Fabric notebook and attach it to lakehouse1.
You need to use PySpark code to transform the data. The solution must meet the following requirements:
* Add a column named pickupDate that will contain only the date portion of pickupDateTime.
* Filter the DataFrame to include only rows where fareAmount is a positive number that is less than 100.
How should you complete the code? To answer, select the appropriate options in the answer area. NOTE:
Each correct selection is worth one point.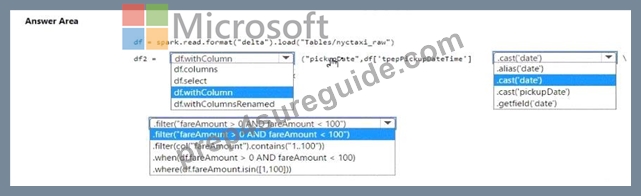
Answer:
Explanation: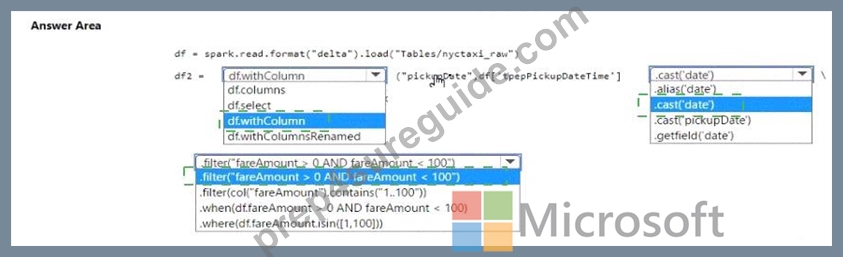
Explanation: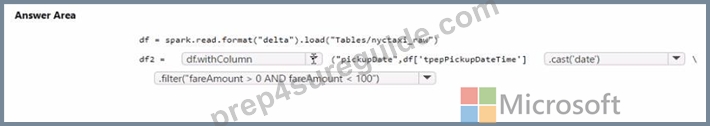
* Add the pickupDate column: .withColumn("pickupDate", df["pickupDateTime"].cast("date"))
* Filter the DataFrame: .filter("fareAmount > 0 AND fareAmount < 100")
In PySpark, you can add a new column to a DataFrame using the .withColumn method, where the first argument is the new column name and the second argument is the expression to generate the content of the new column. Here, we use the .cast("date") function to extract only the date part from a timestamp. To filter the DataFrame, you use the .filter method with a condition that selects rows where fareAmount is greater than 0 and less than 100, thus ensuring only positive values less than 100 are included.
NEW QUESTION # 100
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a Fabric tenant that contains a semantic model named Model1.
You discover that the following query performs slowly against Model1.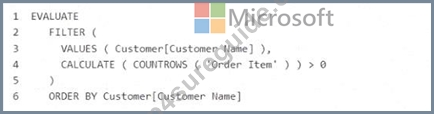
You need to reduce the execution time of the query.
Solution: You replace line 4 by using the following code:
Does this meet the goal?
- A. No
- B. Yes
Answer: A
Explanation:
The suggested replacement does not improve performance. COUNTROWS('Order Item') < 0 is always false (row counts cannot be negative), so the NOT will always evaluate to true. This means the filter condition becomes non-selective and would return all customers, not just those with orders. Therefore, it does not meet the optimization goal.
NEW QUESTION # 101
You have a Fabric tenant that contains a lakehouse.
You are using a Fabric notebook to save a large DataFrame by using the following code.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.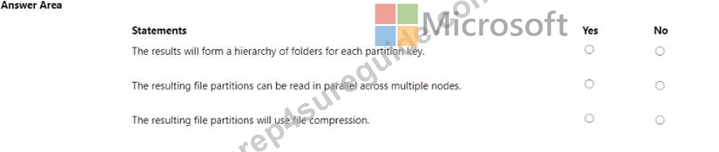
Answer:
Explanation: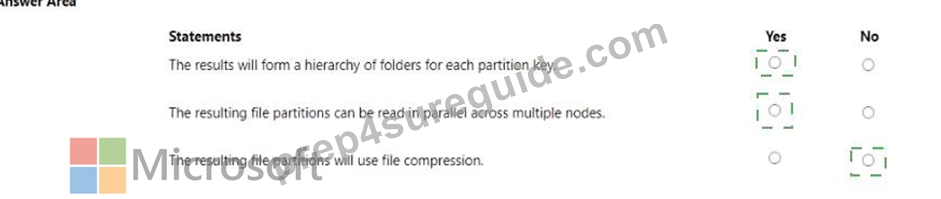
Explanation:
The results will form a hierarchy of folders for each partition key. - Yes The resulting file partitions can be read in parallel across multiple nodes. - Yes The resulting file partitions will use file compression. - No Partitioning data by columns such as year, month, and day, as shown in the DataFrame write operation, organizes the output into a directory hierarchy that reflects the partitioning structure. This organization can improve the performance of read operations, as queries that filter by the partitioned columns can scan only the relevant directories. Moreover, partitioning facilitates parallelism because each partition can be processed independently across different nodes in a distributed system like Spark. However, the code snippet provided does not explicitly specify that file compression should be used, so we cannot assume that the output will be compressed without additional context.
References =
DataFrame write partitionBy
Apache Spark optimization with partitioning
NEW QUESTION # 102
You have a Fabric tenant that contains 30 CSV files in OneLake. The files are updated daily.
You create a Microsoft Power BI semantic model named Model1 that uses the CSV files as a data source. You configure incremental refresh for Model1 and publish the model to a Premium capacity in the Fabric tenant.
When you initiate a refresh of Model1, the refresh fails after running out of resources.
What is a possible cause of the failure?
- A. Query folding is occurring.
- B. XMLA Endpoint is set to Read Only.
- C. Only refresh complete days is selected.
- D. The delta type of the column used to partition the data has changed.
- E. Query folding is NOT occurring.
Answer: E
Explanation:
https://learn.microsoft.com/en-us/power-bi/connect-data/incremental-refresh- troubleshoot#problem-loading-data-takes-too-long
NEW QUESTION # 103
You have a Fabric tenant that contains a complex semantic model. The model is based on a star schema and contains many tables, including a fact table named Sales.
You need to visualize a diagram of the model. The diagram must contain only the Sales table and related tables.
What should you use from Microsoft Power BI Desktop?
- A. data categories
- B. DAX query view
- C. Model view
- D. Data view
Answer: C
Explanation:
The Model view in Microsoft Power BI Desktop allows you to visualize the relationships between tables in a semantic model. It displays a diagram of the data model, where you can focus on specific tables, such as the Sales fact table and its related tables, by arranging or filtering the view. This is the ideal tool for analyzing the structure of a star schema and understanding table relationships.
NEW QUESTION # 104
You have a Fabric warehouse named Warehousel that contains a table named Table! Tablel contains customer data.
You need to implement row-level security (RLS) for Tablel. The solution must ensure that users can see only their respective data.
Which two objects should you create? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
- A. SECURITY POLICY
- B. CONSTRAINT
- C. DATABASE ROLE
- D. FUNCTION
- E. STORED PROCEDURE
Answer: A,D
Explanation:
To implement row-level security (RLS) in a Fabric Warehouse (like in Azure Synapse or SQL Server):
You must define a predicate function (usually an inline table-valued function) that filters rows for each user
# Function.
Then you bind that function to the table using a Security Policy # Security Policy.
A Database Role is used for group-based access control but not specifically for implementing RLS.
Stored procedures and constraints are not used for RLS.
Correct answers: A and D
Reference: Row-Level Security (RLS) in Synapse/Fabric SQL
NEW QUESTION # 105
Drag and Drop Question
You are building a solution by using a Fabric notebook.
You have a Spark DataFrame assigned to a variable named df. The DataFrame returns four columns.
You need to change the data type of a string column named Age to integer. The solution must return a DataFrame that includes all the columns.
How should you complete the code? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.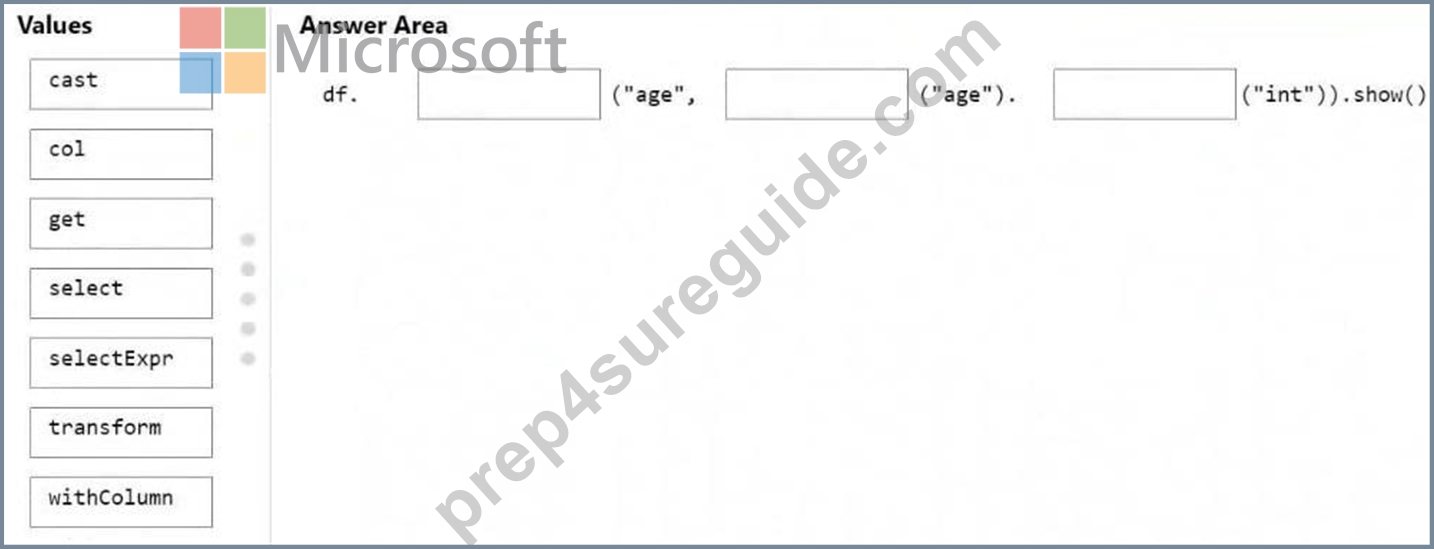
Answer:
Explanation: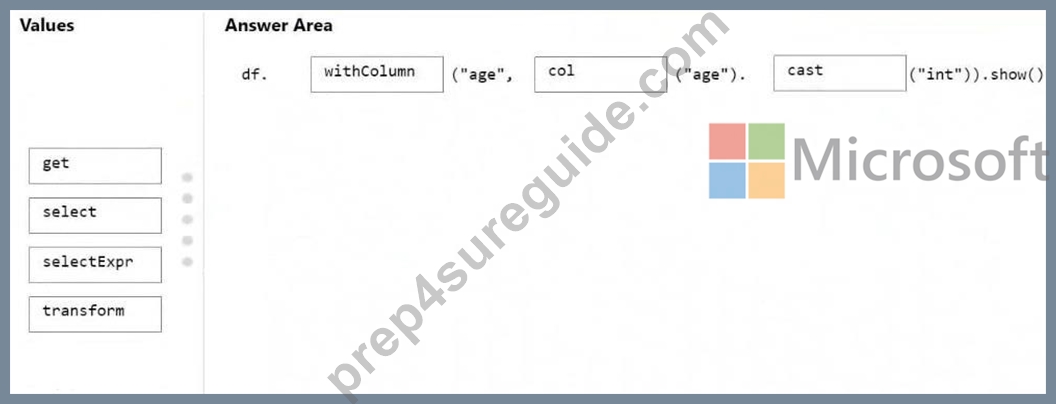
NEW QUESTION # 106
You have a Fabric tenant that contains JSON files in OneLake. The files have one billion items.
You plan to perform time series analysis of the items.
You need to transform the data, visualize the data to find insights, perform anomaly detection, and share the insights with other business users. The solution must meet the following requirements:
* Use parallel processing.
* Minimize the duplication of data.
* Minimize how long it takes to load the data.
What should you use to transform and visualize the data?
- A. the pandas library in a Fabric notebook
- B. the PySpark library in a Fabric notebook
- C. a Microsoft Power B1 report that uses core visuals
Answer: B
NEW QUESTION # 107
You have a Fabric tenant that contains a lakehouse named Lakehouse1
Readings from 100 loT devices are appended to a Delta table in Lakehouse1. Each set of readings is approximately 25 KB. Approximately 10 GB of data is received daily.
All the table and SparkSession settings are set to the default.
You discover that queries are slow to execute. In addition, the lakehouse storage contains data and log files that are no longer used.
You need to remove the files that are no longer used and combine small files into larger files with a target size of 1 GB per file.
What should you do? To answer, drag the appropriate actions to the correct requirements. Each action may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.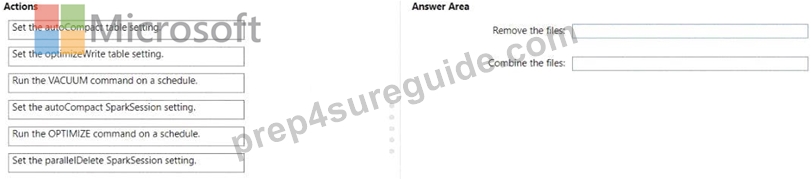
Answer:
Explanation: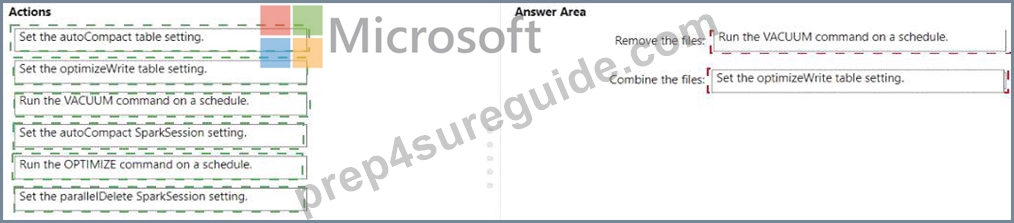
Explanation:
* Remove the files: Run the VACUUM command on a schedule.
* Combine the files: Set the optimizeWrite table setting. or Run the OPTIMIZE command on a schedule.
To remove files that are no longer used, the VACUUM command is used in Delta Lake to clean up invalid files from a table. To combine smaller files into larger ones, you can either set the optimizeWrite setting to combine files during write operations or use the OPTIMIZE command, which is a Delta Lake operation used to compact small files into larger ones.
NEW QUESTION # 108
You have a Fabric tenant that contains a Microsoft Power BI report named Report1. Report1 includes a Python visual.
Data displayed by the visual is grouped automatically and duplicate rows are NOT displayed.
You need all rows to appear in the visual.
What should you do?
- A. Add a unique field to each row.
- B. Reference the columns in the Python code by index.
- C. Modify the Sort Column By property for all columns.
- D. Modify the Summarize By property for all columns.
Answer: D
Explanation:
By setting the "Summarize By" property to "None" for all columns, you disable automatic aggregation and ensure all rows, including duplicates, are displayed in the Python visual.
NEW QUESTION # 109
You have a Fabric workspace named Workspace1 and an Azure Data Lake Storage Gen2 account named storage"!. Workspace1 contains a lakehouse named Lakehouse1.
You need to create a shortcut to storage! in Lakehouse1.
Which connection and endpoint should you specify? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.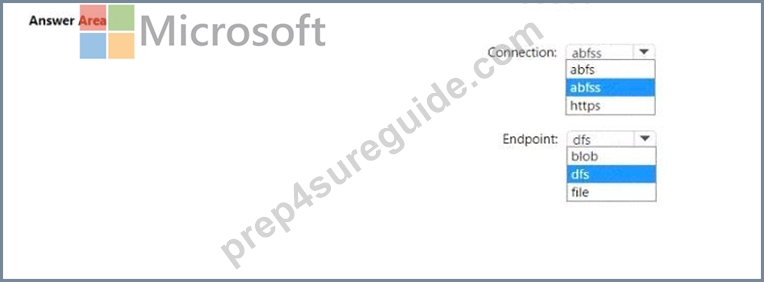
Answer:
Explanation: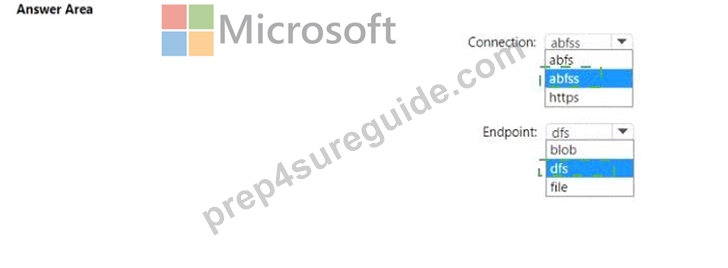
Explanation: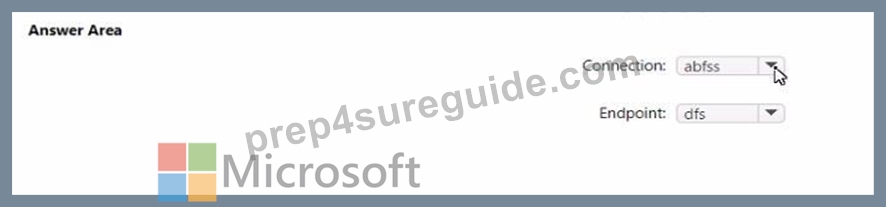
When creating a shortcut to an Azure Data Lake Storage Gen2 account in a lakehouse, you should use the abfss (Azure Blob File System Secure) connection string and the dfs (Data Lake File System) endpoint. The abfss is used for secure access to Azure Data Lake Storage, and the dfs endpoint indicates that the Data Lake Storage Gen2 capabilities are to be used.
NEW QUESTION # 110
You have a Fabric workspace named Workspace1 and an Azure Data Lake Storage Gen2 account named storage"!. Workspace1 contains a lakehouse named Lakehouse1.
You need to create a shortcut to storage! in Lakehouse1.
Which connection and endpoint should you specify? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.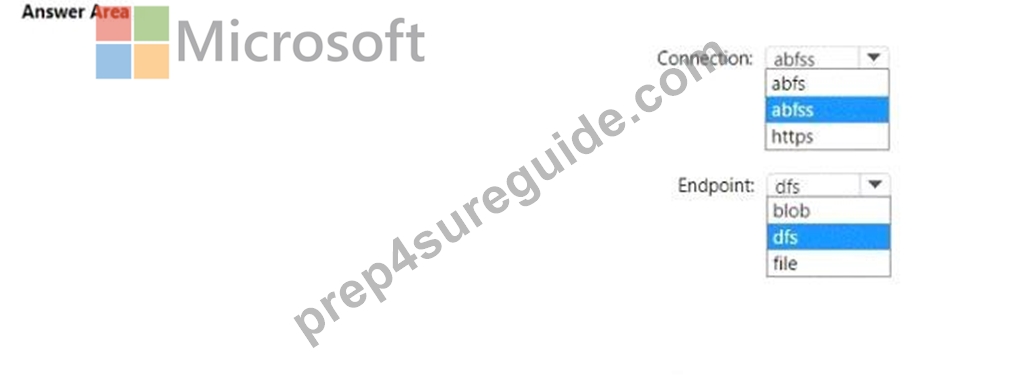
Answer:
Explanation: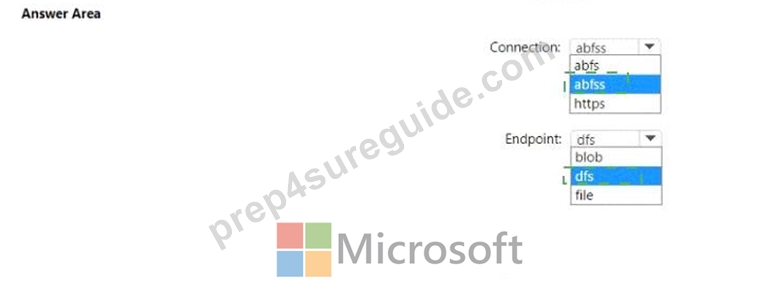
Explanation: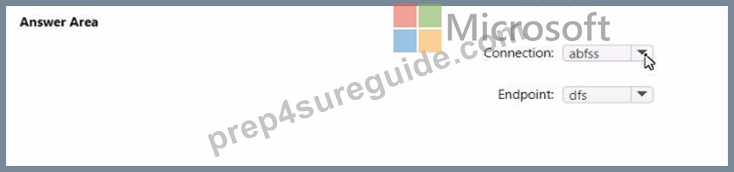
When creating a shortcut to an Azure Data Lake Storage Gen2 account in a lakehouse, you should use the abfss (Azure Blob File System Secure) connection string and the dfs (Data Lake File System) endpoint. The abfss is used for secure access to Azure Data Lake Storage, and the dfs endpoint indicates that the Data Lake Storage Gen2 capabilities are to be used.
NEW QUESTION # 111
You have a Fabric warehouse that contains a table named Sales.Orders. Sales.Orders contains the following columns.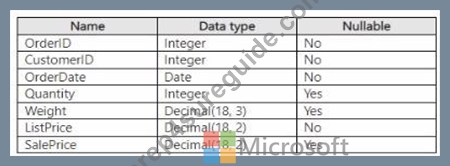
You need to write a T-SQL query that will return the following columns.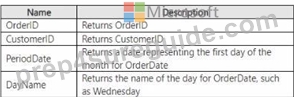
How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.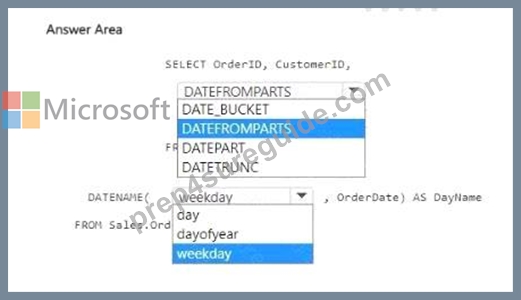
Answer:
Explanation: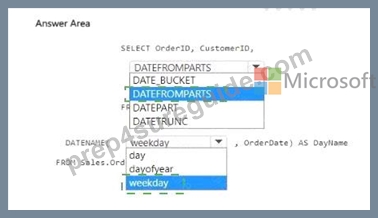
Explanation: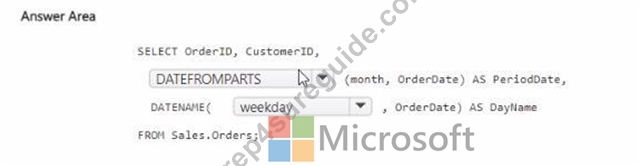
For the PeriodDate that returns the first day of the month for OrderDate, you should use DATEFROMPARTS as it allows you to construct a date from its individual components (year, month, day).
For the DayName that returns the name of the day for OrderDate, you should use DATENAME with the weekday date part to get the full name of the weekday.
The complete SQL query should look like this:
SELECT OrderID, CustomerID,
DATEFROMPARTS(YEAR(OrderDate), MONTH(OrderDate), 1) AS PeriodDate,
DATENAME(weekday, OrderDate) AS DayName
FROM Sales.Orders
Select DATEFROMPARTS for the PeriodDate and weekday for the DayName in the answer area.
NEW QUESTION # 112
You have a Fabric tenant.
You are creating a Fabric Data Factory pipeline.
You have a stored procedure that returns the number of active customers and their average sales for the current month.
You need to add an activity that will execute the stored procedure in a warehouse. The returned values must be available to the downstream activities of the pipeline.
Which type of activity should you add?
- A. Copy data
- B. Lookup
- C. Get metadata
- D. Stored procedure
Answer: B
Explanation:
In a Fabric Data Factory pipeline, to execute a stored procedure and make the returned values available for downstream activities, the Lookup activity is used. This activity can retrieve a dataset from a data store and pass it on for further processing. Here's how you would use the Lookup activity in this context:
* Add a Lookup activity to your pipeline.
* Configure the Lookup activity to use the stored procedure by providing the necessary SQL statement or stored procedure name.
* In the settings, specify that the activity should use the stored procedure mode.
* Once the stored procedure executes, the Lookup activity will capture the results and make them available in the pipeline's memory.
* Downstream activities can then reference the output of the Lookup activity.
References: The functionality and use of Lookup activity within Azure Data Factory is documented in Microsoft's official documentation for Azure Data Factory, under the section for pipeline activities.
NEW QUESTION # 113
You have a Fabric workspace named Workspace1 that contains a dataflow named Dataflow1.
Dataflow1 has a query that returns 2,000 rows.
You view the query in Power Query as shown in the following exhibit.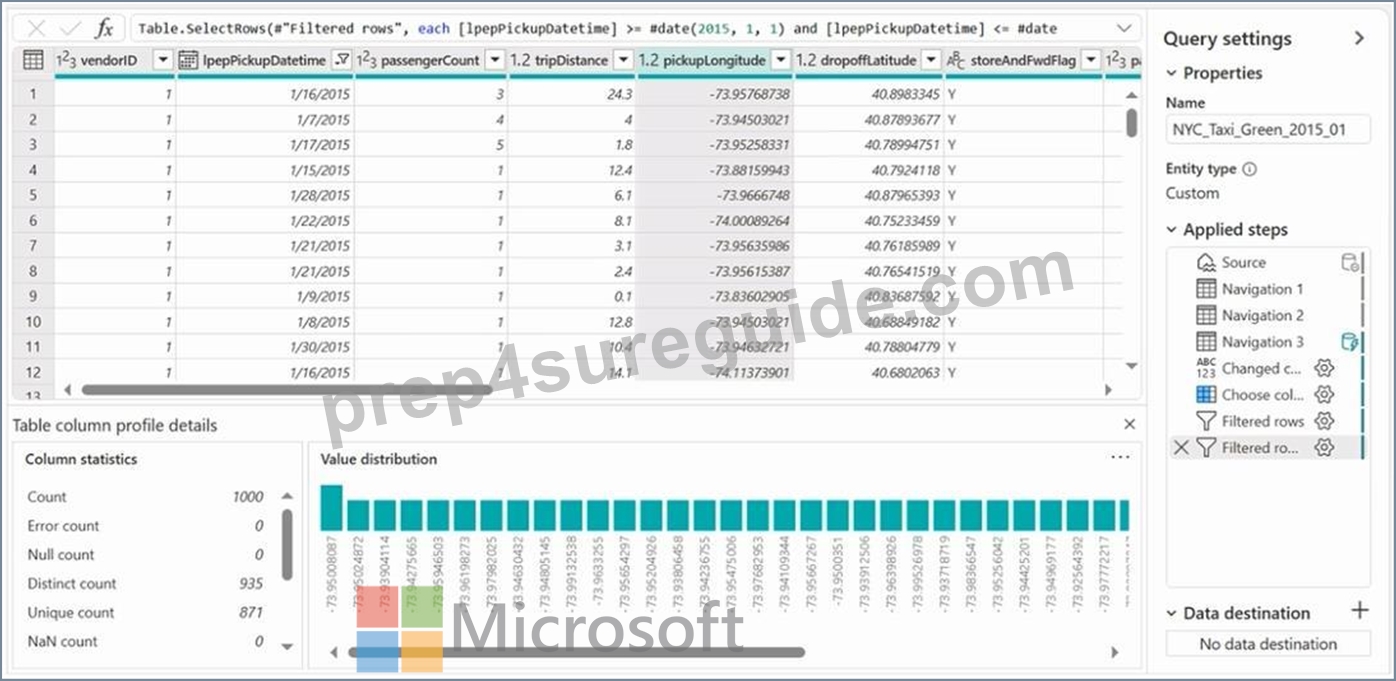
What can you identify about the pickupLongitude column?
- A. The column has missing values.
- B. All the table rows are profiled.
- C. There are 935 values that occur only once.
- D. The column has duplicate values.
Answer: D
NEW QUESTION # 114
You have a semantic model named Modelt that contains data that relates to customers and their bank account balances.
Model1 has the following tables and columns.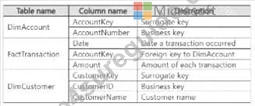
A customer can have one or more accounts. Each account can be associated to multiple customers.
You need to ensure that users can query Model1 to identify the total transaction amounts by customer.
What should you add to Model1?
- A. A many-to-many relationship between FactTransaction and DimCustomer
- B. A bridge table with relationships to DimCustomer and DimAccount
- C. A bridge table with relationships to FactTransaction and DimCustomer
- D. The CustomerKey column in FactTransaction and a relationship to DimCustomer
Answer: C
NEW QUESTION # 115
You have a Fabric workspace named Workspace 1 that contains a dataflow named Dataflow1. Dataflow! has a query that returns 2.000 rows. You view the query in Power Query as shown in the following exhibit.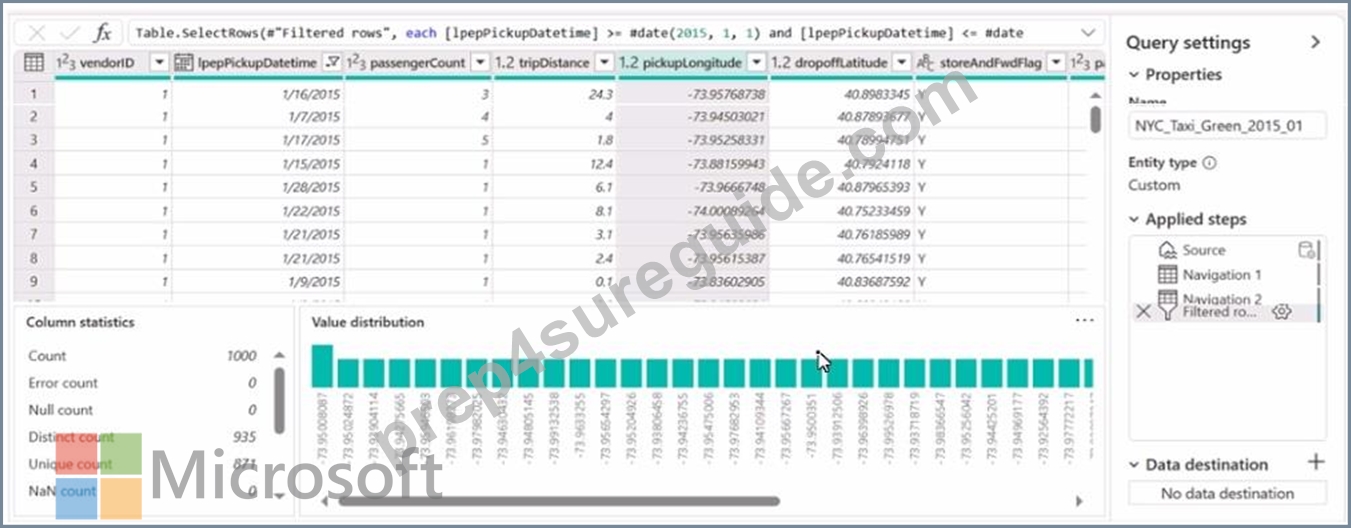
What can you identify about the pickupLongitude column?
- A. The column has missing values.
- B. All the table rows are profiled.
- C. There are 935 values that occur only once.
- D. The column has duplicate values.
Answer: D
Explanation:
The pickupLongitude column has duplicate values. This can be inferred because the 'Distinct count' is 935 while the 'Count' is 1000, indicating that there are repeated values within the column. References = Microsoft Power BI documentation on data profiling could provide further insights into understanding and interpreting column statistics like these.
NEW QUESTION # 116
......
Pass Your DP-600 Dumps as PDF Updated on 2026 With 166 Questions: https://www.prep4sureguide.com/DP-600-prep4sure-exam-guide.html
Microsoft DP-600 Real Exam Questions and Answers FREE: https://drive.google.com/open?id=16vk8lkDgSvjo-UbjLWSRnCCpm8pfJ7IT